What Is a URL? Parts, Examples & How Web Addresses Work
Key takeaway: A URL (Uniform Resource Locator) is the human-readable address of a unique resource on the internet. It has six parts — scheme, subdomain, domain, path, query parameters, and fragment — that together tell your browser exactly what to fetch and where. Short, lowercase, hyphenated URLs with HTTPS are easier to trust, share, and rank.
Every time you click a link, bookmark an article, or type a web address into your browser, you are using a URL. Short for Uniform Resource Locator, a URL is the human-readable address assigned to a unique resource on the internet—whether that resource is an HTML webpage, an image, a PDF document, or a video stream. According to MDN Web Docs, browsers rely on URLs as their primary mechanism to locate and retrieve published content from web servers worldwide.
Without URLs, navigating the web would require memorizing numerical IP addresses (such as 192.0.2.1) for every website. At USABite, where we explain core technology concepts in practical, bite-sized guides, understanding how a web address works helps you browse more safely, fix broken links, and structure cleaner websites.
What Does URL Stand For and How Did It Start?
The acronym URL stands for Uniform Resource Locator. Computer scientist Tim Berners-Lee created the URL while developing the World Wide Web so hypertext documents could link to one another using a single addressing format across different network protocols. As documented in Cloudflare’s history of the URL, the specification was first published by the Internet Engineering Task Force (IETF) in December 1994 under RFC 1738.
In January 2005, Tim Berners-Lee, Roy Fielding, and Larry Masinter updated the syntax in IETF RFC 3986 (Internet Standard 66), which governs Uniform Resource Identifiers (URIs). While a URI identifies a resource by name or location, a URL specifically tells your browser how and where to retrieve it over a network.
The Anatomy of a URL: Every Component Explained
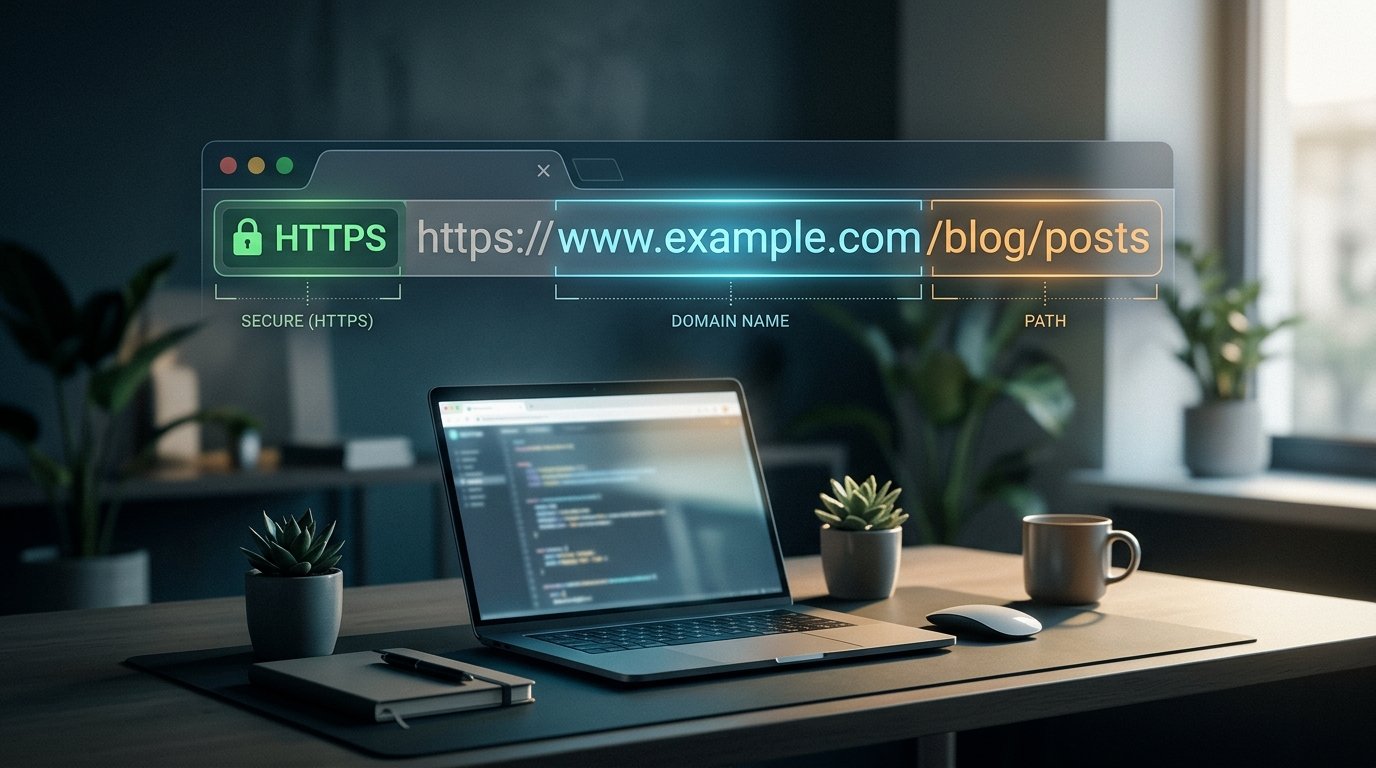
A long web link can look like a complex string of slashes, question marks, and hyphens. However, web.dev’s guide to URL parts shows that every standard web address follows a
predictable, left-to-right syntax. Consider this complete example:
https://www.usabite.com/guides/what-is-a-url?utm_source=newsletter#anatomy
Each segment of that address serves a distinct role when your browser requests the page:
| URL Component | Example Segment | Primary Function |
|---|---|---|
| 1. Scheme (Protocol) | https:// | Specifies the communication protocol (such as encrypted HTTPS) used to request the resource. |
| 2. Subdomain | www. | Organizes a subdivision of the main domain (common examples include www, blog, or shop). |
| 3. Domain Name & TLD | usabite.com | Identifies the human-readable site name (usabite) and its top-level domain extension (.com). |
| 4. Path & URL Slug | /guides/what-is-a-url | Points to the subfolder hierarchy (/guides/) and exact page slug (what-is-a-url) on the server. |
| 5. Query Parameters | ?utm_source=newsletter | Passes key-value pairs after a question mark (?) for filtering, search queries, pagination, or analytics. |
| 6. Fragment (Anchor) | #anatomy | Scrolls the browser directly to a specific heading ID inside the loaded webpage. |
1. The Scheme or Protocol (HTTP vs. HTTPS)
The scheme sits at the start of a URL, followed by a colon and two forward slashes (://). Modern sites use https:// (Hypertext Transfer Protocol Secure) to encrypt browser-to-server traffic via TLS/SSL. As Moz’s URL guide notes, specialized schemes like mailto: and ftp: handle email links and file transfers.
2. The Domain Name and Top-Level Domain (TLD)
Right after the protocol comes the domain name (or hostname), which identifies which server hosts the content. It pairs a second-level name (like google or usabite) with a Top-Level Domain (TLD) such as .com, .org, .edu, or country-code extensions like .uk and .ca.
3. The Path, Subfolders, and Page Slug
According to Semrush, everything after the first single slash (/) forms the path, showing where a page lives on the server—such as the /about-us/ slug on our About USABite editorial page.
4. Query Parameters and URL Fragments
Text after a question mark (?) forms a query string of key-value pairs (like ?category=tech&sort=latest). WooRank notes that sites use parameters for filtering, pagination (?page=2), and tracking, while a hash (#) jumps to a section on the same page.
How a URL Works Behind the Scenes
Typing a web address and pressing Enter triggers a four-step lookup across the internet in milliseconds:
- URL Parsing: Your browser parses the address string using rules defined in the MDN URL interface, separating the scheme, hostname, and path.
- DNS Lookup: Your browser contacts a Domain Name System (DNS) resolver to translate the human-readable domain name into its matching numerical IP address.
- TLS Handshake & HTTP Request: The browser connects to that IP address, verifies the SSL certificate if the URL uses
https://, and sends an HTTPGETrequest for the path. - Server Response: The web server replies with an HTTP status code (such as
200 OKwhen found, or404 Not Foundif moved) and sends the HTML, CSS, and media files to render the page.
Common Types of URLs You Will Encounter
Developers and site publishers work with four practical URL types depending on how pages link together, as outlined by W3C HTML specifications and Moz:
- Absolute URLs: Include the complete web address from protocol to path (such as
https://usabite.com/contact-us/), which is required when linking to an external website. - Relative URLs: Contain only the path segment (such as
/contact-us/) because the browser automatically assumes the current domain. - Canonical URLs: Specify the single preferred master address when duplicate or filtered versions of a page exist, preventing split search rankings.
- Semantic URLs: Use plain, readable words (like
/guides/what-is-a-url) rather than cryptic database IDs like/index.php?id=84920.
Why URL Structure Matters for SEO and User Trust
A well-organized URL helps both human readers and search engines understand your page before they click. According to the Google Search Central SEO Starter Guide, Google displays parts of the URL path as breadcrumbs in search results so users can quickly gauge whether a page is relevant.
Following the Google Search Central URL Structure Best Practices and research from Page One Power keeps your WordPress permalinks clean and crawlable:
- Use descriptive, natural words: Include your core topic in the URL slug so readers know what the page covers, without stuffing repetitive keywords.
- Separate words with hyphens, not underscores: Search engines read hyphens (
what-is-a-url) as word separators, whereas underscores (what_is_a_url) join words together. - Stick to lowercase letters: Because servers can treat uppercase and lowercase paths as different URLs, lowercase slugs prevent duplicate-content errors.
- Keep slugs concise and evergreen: Remove filler words and dates so your URL stays accurate when updated later and remains well under the 2,083-character browser limit.
Have a question about how web technologies work or want to suggest a future tutorial? Reach out anytime via the Contact USABite page as we continue expanding our library of practical tech explainers.
Frequently Asked Questions
What does URL stand for?
URL stands for Uniform Resource Locator. It is the human-readable address assigned to a unique resource on the internet, such as a webpage, an image, a PDF, or a video stream.
What are the six parts of a URL?
A complete URL has six parts: the scheme (such as https://), the subdomain (such as www.), the domain name and top-level domain (such as usabite.com), the path (/guides/what-is-a-url), query parameters (?utm_source=newsletter), and the fragment (#anatomy), which jumps to a specific heading on the page.
What is the difference between a URL and a URI?
A URI (Uniform Resource Identifier) identifies a resource by name or location, while a URL is a type of URI that also tells your browser how and where to retrieve it over a network. The syntax for both is defined in IETF RFC 3986.
How long can a URL be?
Browsers generally handle URLs up to about 2,083 characters. Keeping slugs short, lowercase, and free of filler words and dates helps a URL stay accurate when the page is updated later.